
Service at a glance
Pandas, NumPy, and Plotly Dashboards for Data-Driven Decision Making
- Data Analysis & Exploration – Deep exploratory data analysis (EDA) with Python, Pandas, NumPy, and Matplotlib to uncover trends, anomalies, and opportunities.
- Machine Learning Models – Scikit-learn, XGBoost, and TensorFlow models for classification, regression, clustering, and recommendation engines.
- Natural Language Processing – Text classification, sentiment analysis, entity recognition, and LLM fine-tuning using HuggingFace and spaCy.
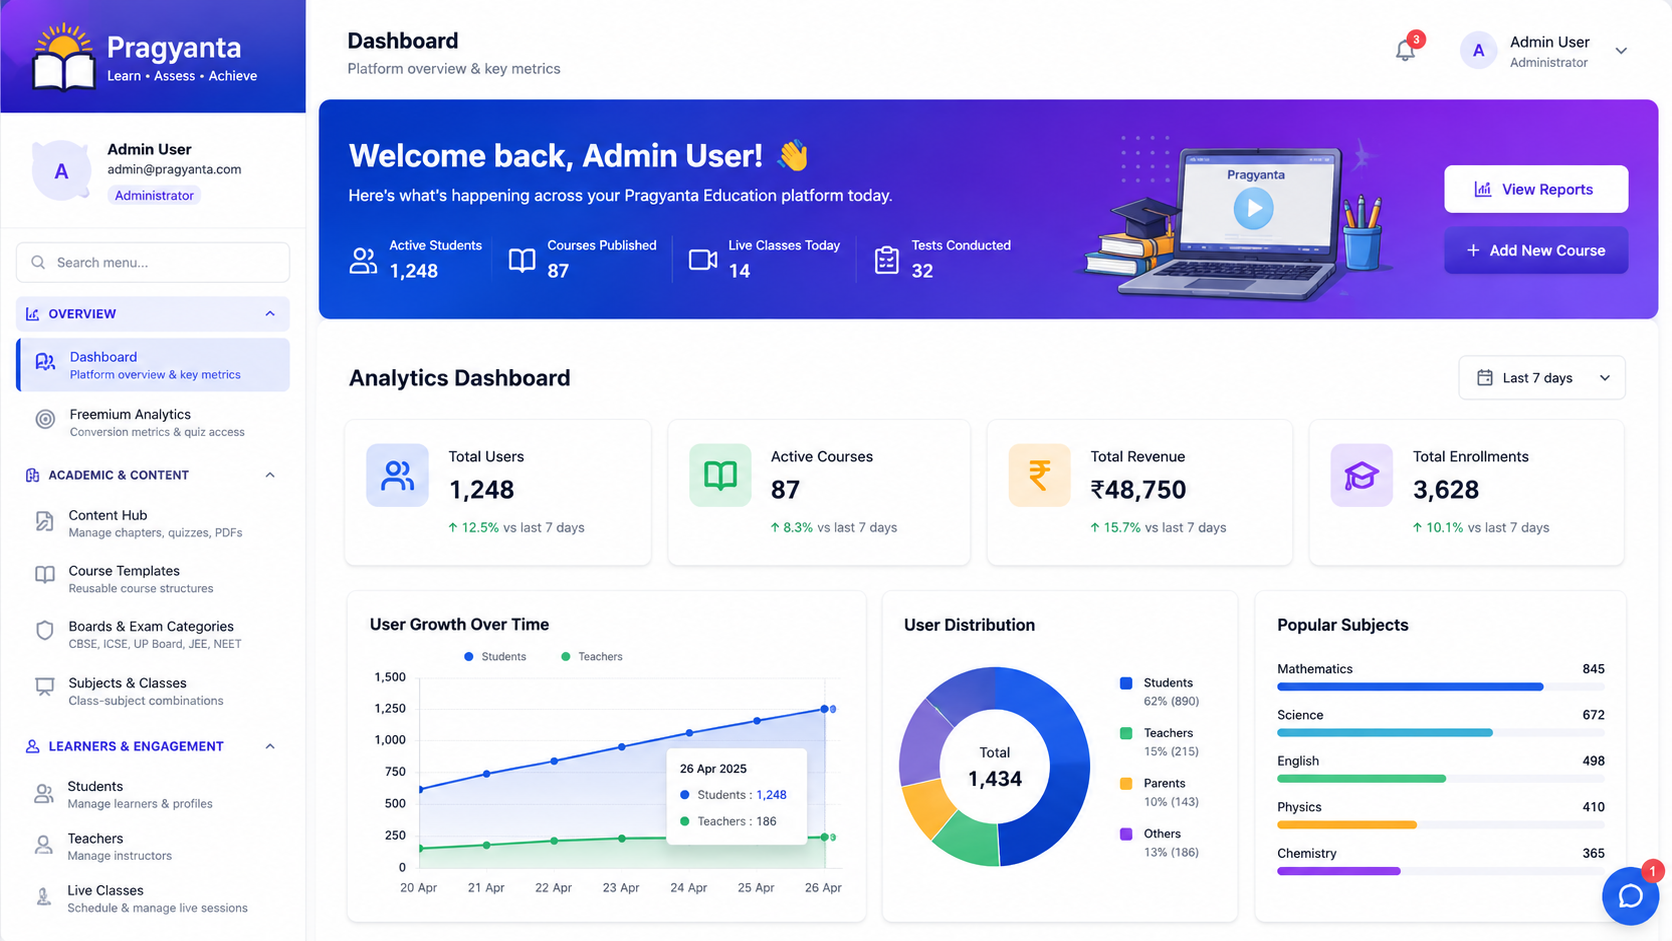
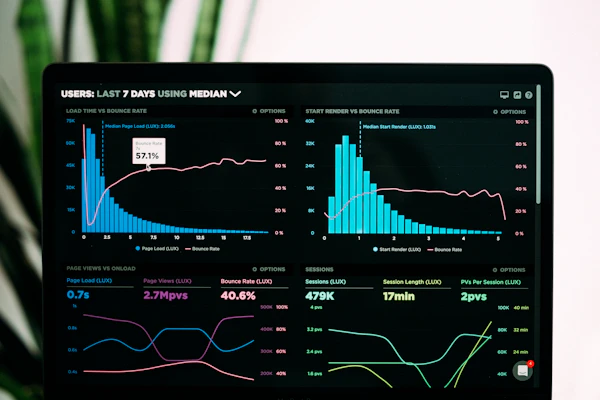
- Data Visualisation – Interactive web dashboards with Plotly, Dash, or Streamlit for real-time data exploration.
- Automated Reporting – Python scripts that generate PDF/Excel reports automatically on a schedule, eliminating manual reporting overhead.
- Data Cleaning & ETL – Preprocessing pipelines for messy, incomplete, or inconsistent datasets from any source format.
- Statistical Analysis – Hypothesis testing, A/B test analysis, regression modelling, and statistical inference for evidence-based decisions.
Turning Raw Data Into Competitive Advantage
Every business collects data — few extract its full value. Our data scientists and analysts use Python's world-class ecosystem to build models and visualisations that answer your hardest business questions. From one-off analyses to production ML systems, we deliver insights you can act on immediately.
One-off analysis versus a production ML system
Those are genuinely different engagements, and we scope them differently. A one-off analysis answers a specific question with a report or notebook; a production ML system needs to run reliably, retrain on new data, and be monitored for drift — an entirely different engineering commitment. We'll tell you honestly which one your actual problem needs rather than over-building a one-time question into unnecessary infrastructure.
Questions we get asked
Do we need a full machine learning model, or would a simpler analysis answer our question?
Often a simpler analysis is enough, and we'll say so — a one-off exploratory analysis answers a specific question directly; a production ML model is a different, larger commitment that's only worth it if the question is genuinely ongoing.
Can you work with messy, incomplete data, or does it need to be clean first?
We expect it to be messy — data cleaning and ETL preprocessing for incomplete or inconsistent datasets is part of the work, not a prerequisite you need to solve first.
Do you build interactive dashboards, or just deliver a static report?
Either, depending on your need — a static report answers a one-off question; an interactive dashboard (Plotly, Dash or Streamlit) suits an ongoing exploration need.
Can you integrate NLP or LLM-based analysis into our existing data pipeline?
Yes — text classification, sentiment analysis and LLM-based analysis using HuggingFace or similar tools can be integrated into an existing pipeline or built as a new one.
How We Deliver
Discovery
We map your goals, users, workflows, integrations, and technical requirements before writing a single line of code.
Solution Design
We define architecture, user flows, data models, integrations, and delivery boundaries before build work accelerates.
Development
Sprint-based build with progress updates, code reviews, and continuous testing.
Launch & Improve
Go-live support, monitoring, operational handover, and iteration once real users begin using the system.
Related Resources
Need help shaping this service into a real delivery plan?
Connect with us to discuss scope, users, integrations, architecture, delivery risks, and the right build path for your business.
Discuss Your Project